Atlas Platform
Process large document uploads with background workers and cloud capacity that adapts to demand.
Documents in. Work moving.
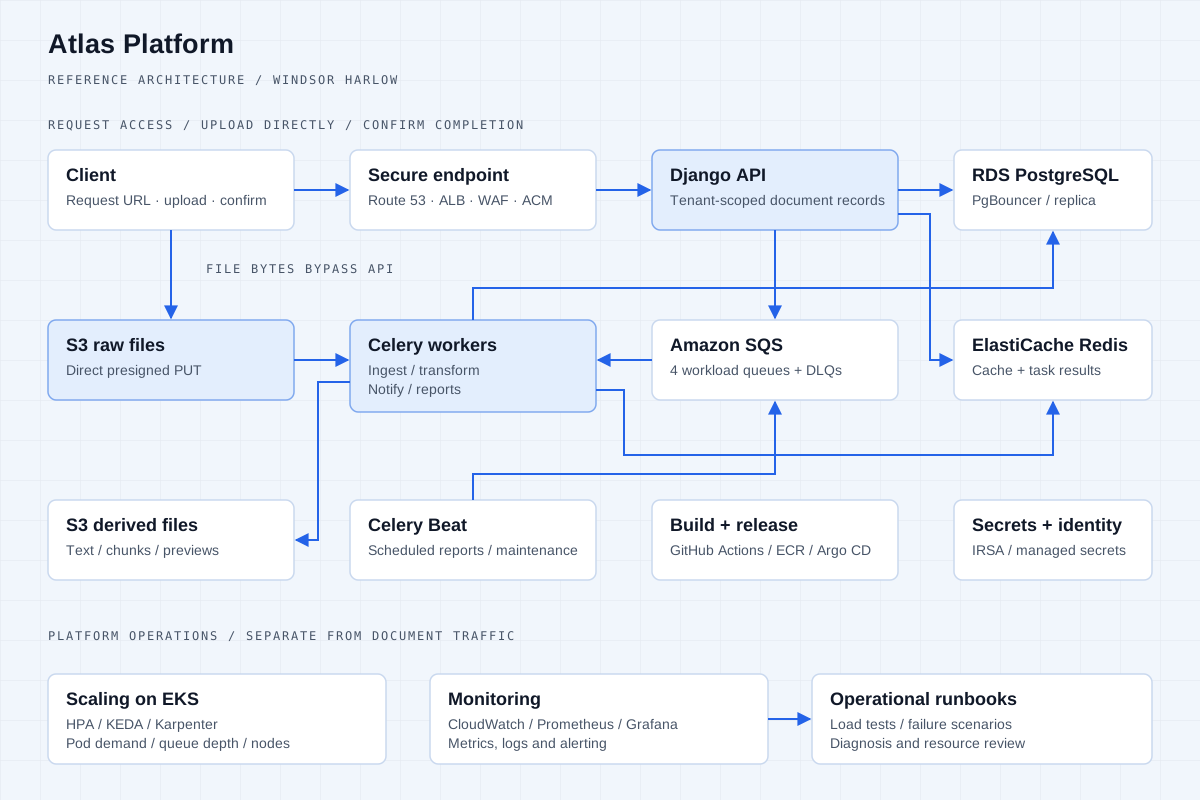
A document-processing platform that keeps each organisation’s records separate. Files upload directly to Amazon S3, while queued background jobs validate documents, extract text, create previews and notify connected systems. It runs on Amazon EKS with autoscaling and operational runbooks.
Decisions that shape the system.
Keep uploads out of the API
Django issues a temporary S3 upload URL. The client sends the file directly to S3, then confirms completion through the API — file bytes never touch the API pods.
Give each workload its own queue
Ingest, transform, notification and reporting jobs use separate SQS queues and Celery workers. Retries are safe, and failed jobs move to dead-letter queues.
Operate the whole path
HPA scales the API, KEDA responds to queued work and Karpenter supplies node capacity. Metrics, load tests and failure scenarios support the runbooks.
What it does.
Direct file uploads
Presigned S3 uploads bypass API pods.
Separate tenant records
Tenant-scoped queries and isolation tests.
Distributed processing
Four SQS queues and Celery workers.
Demand-based capacity
HPA, KEDA and Karpenter.
Workload security
Scoped identities, managed secrets, encryption.
Operational practice
Load tests, failure scenarios, runbooks.
Built with.
Engineering lab — an independent reference build, not client work. Text extraction and chunking are implemented; the embedding step is a placeholder.
Polyglot Microservices Pipeline